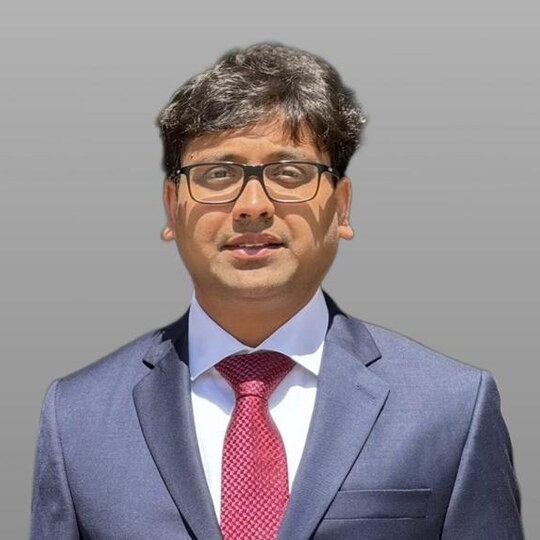
Indranil Halder is a Research Associate at the Harvard John A. Paulson School of Engineering and Applied Sciences. Previously, Indranil was the Harvard Quantum Initiative Fellow at the Center for the Fundamental Laws of Nature.
Indranil is a machine learning researcher specializing in generative AI, with core interests in the interpretability of knowledge representations and the safety and robustness of deep learning systems.
Research
Machine learning
Large language models are now deployed in a wide range of high-stakes applications, which makes a precise understanding of their failure modes as important as continued improvements in their capabilities. Indranil’s research in machine learning aims to identify and quantify the mechanisms by which these systems can fail or be exploited. His approach is to develop analytically tractable theoretical models that yield quantitative predictions, which are then tested in experiments with large language models. The topics below are ordered by the stage at which the corresponding vulnerability arises: pre-training, inference-time selection, adversarial prompting, and the processing of long contexts.
Data poisoning. Web-scale pre-training corpora cannot be curated exhaustively, and a small fraction of corrupted data may therefore be incorporated into training. Existing studies have focused largely on targeted backdoors and their persistence through safety post-training. Indranil and collaborators address a more fundamental question: how performance on clean data degrades as a function of the poison rate. Controlled pre-training experiments exhibit power-law degradation with a non-integer exponent, and the work develops a solvable theory that accounts for this behavior.
Reward hacking. The performance of language models is increasingly improved at inference time by generating multiple candidate responses and selecting among them with a judge model. Because the judge is an imperfect proxy for response quality, additional search may exploit its deficiencies rather than improve the underlying output, a phenomenon known as reward hacking. Indranil’s analytically tractable model of the LLM-as-a-Judge setting characterizes the conditions under which additional inference-time computation yields monotonic improvement and those under which there exists a finite optimal number of samples.
Jailbreaking attacks. Repeated sampling also amplifies safety failures, since a small per-generation probability of an unsafe response accumulates over many attempts. Indranil and collaborators demonstrate that the probability of a successful jailbreak obeys qualitatively distinct scaling laws, polynomial or exponential in the number of samples, depending on the strength of the attack. The crossover between these regimes is explained by a random graph model of binary language generation.
Long context failure. The reliability of deployed systems further depends on their ability to retrieve and use relevant information from increasingly long contexts. Language models exhibit a systematic positional bias and frequently fail to use information located in the middle of the input, a behavior known as the “lost in the middle” phenomenon. A theoretical understanding of this bias is essential for systems that must recall critical facts and maintain persistent memory without becoming susceptible to hallucination. Indranil is also interested in, and actively working on, related topics.
Theoretical physics
Prior to his work in machine learning, Indranil conducted research in theoretical high energy physics. At Harvard University, he established a strong–weak duality closely related to the ER=EPR conjecture, which relates quantum entanglement to spacetime geometry. Using this duality, he made progress on the long-standing problem of accounting for the thermal entropy of black holes in terms of microstates in string theory. He also played a leading role in the study of supersymmetric black holes and black rings in M-theory and F-theory compactifications. In addition, he proposed a framework for evaluating the supersymmetric index of disordered quantum field theories in terms of bi-local fields, which are closely related to wormhole physics.
Publications
Preprint 2026.
Pre-training data poisoning of large language models is usually studied through targeted backdoors and their survival through safety post-training. This work asks a more basic question: how does a model’s clean-data performance degrade as the poison rate \(\varepsilon\) grows? In controlled pre-training runs of OLMo-style models, the relative increase \(\Delta\) in clean-data validation perplexity between poisoned and clean models, matched in architecture, token budget and optimization schedule, is well fit by a power law \(\Delta \approx C\varepsilon^{a}\) with a non-integer exponent.
The paper first proves an analyticity barrier: whenever the contaminated objective depends analytically on \(\varepsilon\) around a nondegenerate clean-data optimum, \(\Delta\) is generically quadratic in \(\varepsilon\), so a non-integer exponent is a signature of genuinely singular structure. That structure is supplied by a solvable model, truncated ridge regression with heavy-tailed covariates controlled by \(q_*\), under label-shift poisoning. The central result is that the excess-risk scaling exponent depends on the order of limits: in the high-dimensional proportional regime it scales as \(\varepsilon^{q_*/(q_*+2)}\), whereas taking the ample-data limit first gives \(\varepsilon^{2-2/q_*}\), and the two limits do not commute. These predictions are confirmed by numerical simulations. Finally, the paper argues that finite training time acts as a poison-dependent truncation of the curvature spectrum in LLM pre-training, and derives the observed scaling law under the modeling hypothesis of a heavy-tailed inverse-curvature spectrum.
Preprint 2026.
This work examines how inference-time scaling changes under adversarial attack. Jailbreak prompts exploit weaknesses in a model’s safety mechanisms, and repeated sampling k times can turn a small per-generation vulnerability into a high probability of attack success at least once, as measured by pass@k. Indranil and collaborators experimentally show that the probability of obtaining an unsafe response can obey qualitatively different scaling laws depending on the strength of the attack. Without a strong attack, the residual safety gap can decay polynomially with the number of samples; under sufficiently strong adversarial prompting, it can instead decay exponentially.
To explain this, the paper develops a generative model of proxy language in terms of a spin-glass system operating in a replica-symmetry-breaking regime, where generations are drawn from the associated Gibbs measure and a subset of low-energy, size-biased clusters is designated unsafe. The jailbreak attack acts like an external field that biases generations toward unsafe clusters. The theory predicts a weak-field regime with power-law scaling and a strong-field regime with exponential scaling, and connects the crossover to the emergence of an ordered phase under strong adversarial attack. These predictions are supported by LLM experiments.
ICML 2026.
Recent advances in large language models increasingly rely on reallocating computation from training to inference through repeated sampling and reward-based search guided by a judge model. While these methods can improve performance, they also create new opportunities for reward hacking: a model may optimize the judge model’s flaws to get better reward while degrading the underlying quality of its outputs. In this paper, Indranil developed a theoretical framework for understanding these effects.
This work shows that, depending on reward misspecification, increasing the number of inference-time samples can either help monotonically or admit a finite optimum, and that for fixed sample count, there is an optimal reward-based selection temperature. In the monotonic domain, the framework predicts a new inference-time scaling law for generalization error that is distinct from pass@k, as it accounts for both the reasoning quality and the final-answer accuracy of model generations. These predictions are validated empirically in the LLM-as-a-Judge setting for mid-sized LLMs.